Private AI that works where you are.

AI that runs in your office, uses the cloud only when you choose, and works inside machines and robots. Built on Qwen models and NVIDIA computers.

  • Led by Thailand's first and only Qwen Ambassador
  • Alibaba Cloud Partner for Hybrid & Cloud Solutions
  • Member of NVIDIA Inception
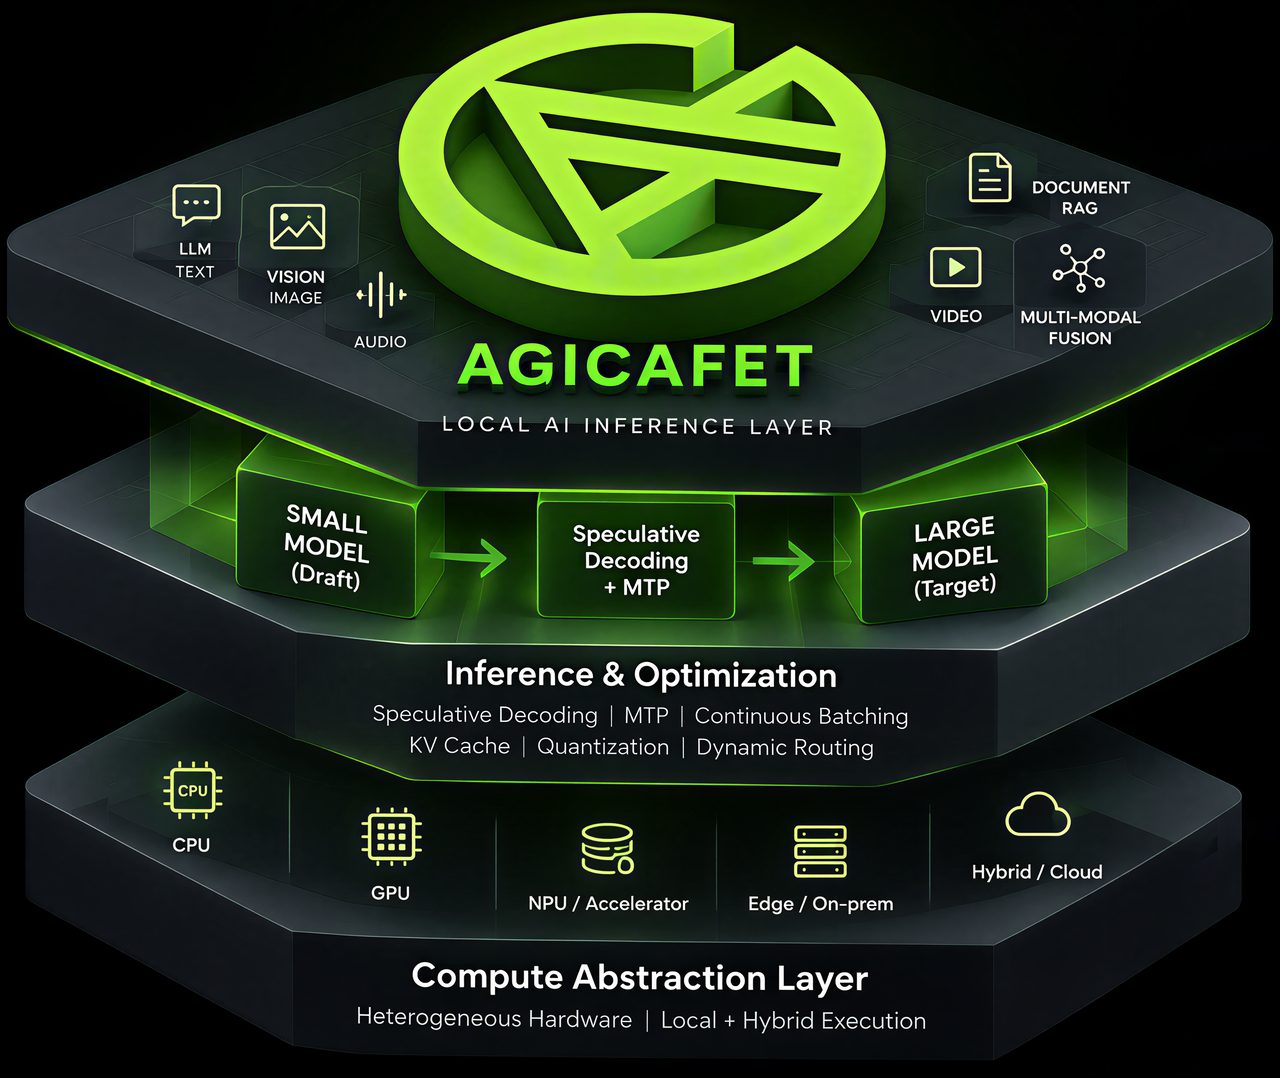
The AGICAFET AI Inference Layer: three stacked layers, with apps and agents on top, the inference engine in the middle and the computers it runs on at the bottom.

Three ways to put AI to work

Choose where your AI runs. We set it up, connect it to your work, and keep it running.

  1. Local AI

    AI inside your building.

    Runs on a machine in your office. Your data never leaves the building.

    Good for: Document Q&A, HR and sales assistants, LINE chatbots

  2. Hybrid AI

    Private first. Cloud when you choose.

    Sensitive work stays on your machine. We can set up very large or very busy jobs to run on Alibaba Cloud, under rules you set.

    Good for: Busy seasons, very large models, many branches

  3. Physical AI

    AI inside machines and robots.

    AI that sees and acts in the real world: robot arms, cameras and drones. It can learn in simulation first, then run on the device.

    Good for: Factories, labs, universities, robot kits for teaching

Robots in our lab

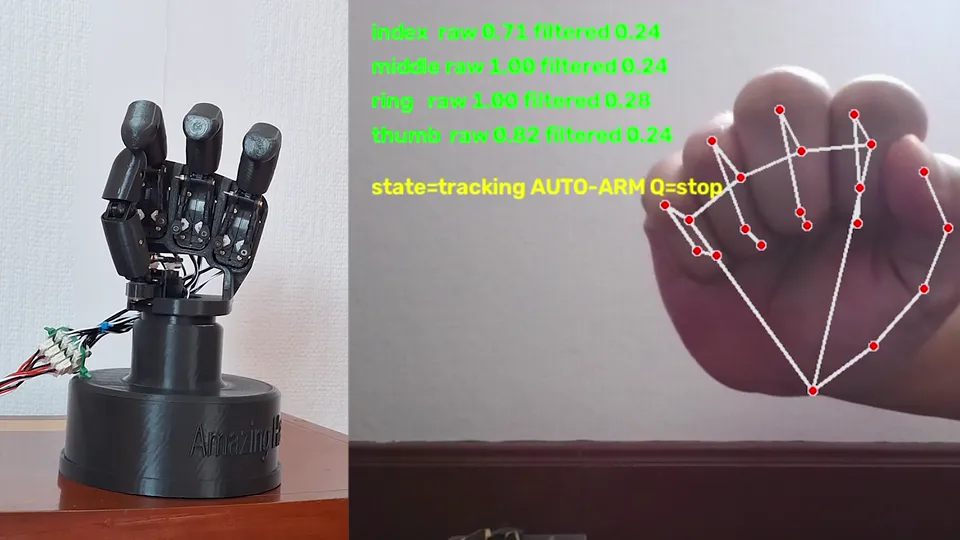
Camera hand-trackingA robot hand mirrors a human hand, live, from a camera.
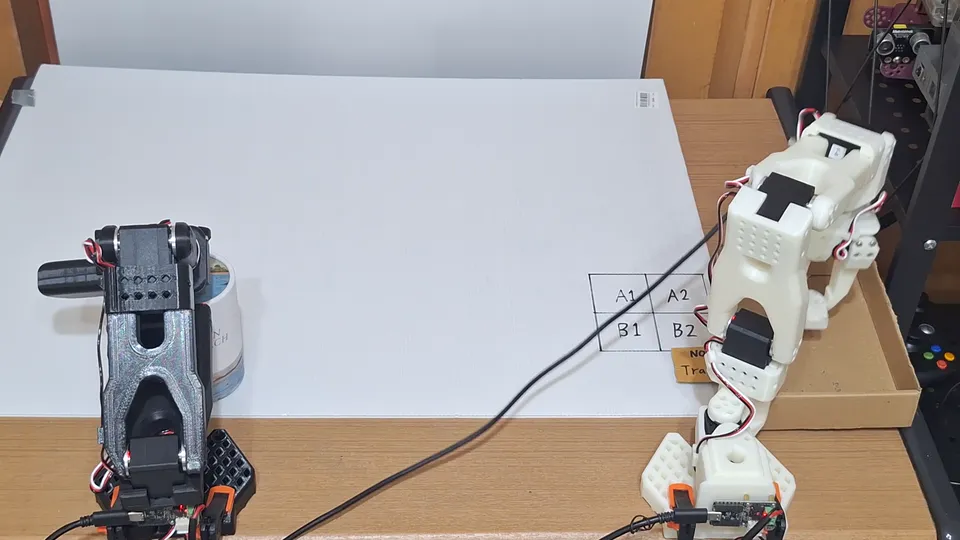
Learned from demonstrationAn arm trained on a few human demos reaches for the target on its own.
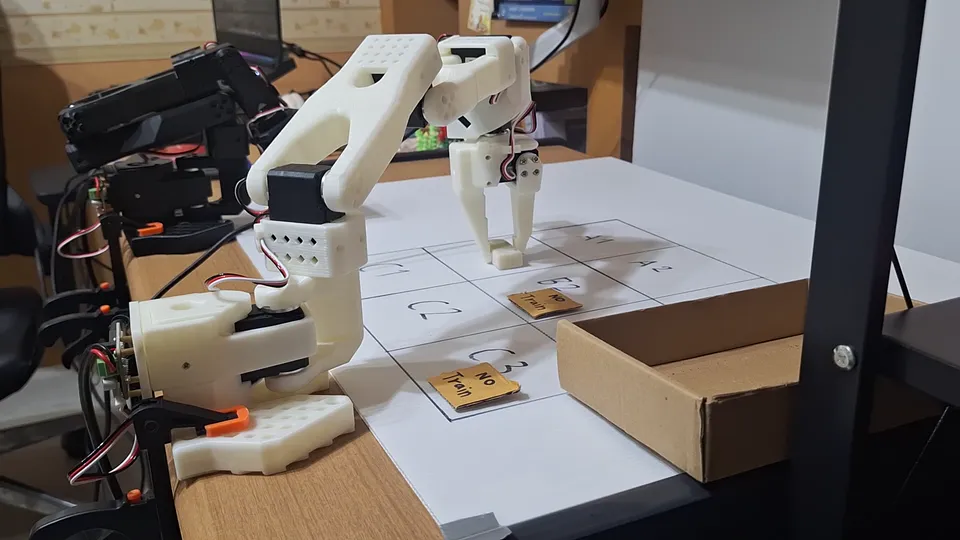
Teach and repeatA taught move, replayed exactly: grip, lift, place.

One system, three layers

Every AGICAFET system has the same three layers. You use the top one. We build, tune and run the two below it, so it stays local, fast, private, and hybrid when you need it.

  1. What you use

    Application & Agents

    Chat assistants, document search that shows its sources, web and LINE chat, and agents that finish tasks for you.

    Multi-Modal
    text, images, audio, video and documents
    Model Flexibility
    small models for quick jobs, large ones for hard ones
  2. What makes it fast

    Inference & Optimization

    The model drafts several words ahead and checks them in one step, so replies come faster with the same quality, and one machine serves many people at once.

    Low Latency
    replies start fast, even when many people use it
    Efficient Compute
    more work from every GPU
  3. Where it runs

    Compute Abstraction Layer

    The same system runs on whatever hardware fits the job, mixing local machines with the cloud when you want it to.

    It runs in three places: Local AI, Hybrid AI, Physical AI.

    Privacy First
    on-device, on-premise or hybrid: you decide
    Production Ready
    we install it, tune it and support it
Technical detail for your IT team
Application & Agents
LLM text · vision · audio · video · document RAG · multi-modal fusion · tool use · function calling · domain apps · hybrid workloads
Inference & Optimization
speculative decoding (draft model or built-in MTP) · continuous batching · KV cache · paged attention · quantization · dynamic routing · TTFT reduction · high throughput
Compute Abstraction Layer
CPU · GPU · NPU / accelerator · edge / on-prem · hybrid / cloud · heterogeneous hardware · local + hybrid execution
Qwen + Alibaba Cloud
Qwen open-weight models · Qwen-Agent · MCP tools · Alibaba Cloud PAI-EAS (Bangkok) · Alibaba Cloud Model Studio
NVIDIA
DGX Spark (GB10 Grace Blackwell) · Jetson · TensorRT-LLM · NVFP4 · Isaac
See the full diagram

Built on Qwen and NVIDIA

Qwen models are the brain. NVIDIA computers are the engine. We put the two together and tune them for your work.

The models

QwenAlibaba Cloud

Open-weight AI models your company can run and keep. The Qwen family lists Thai among its languages; newer Qwen models also read images and answer faster with built-in Multi-Token Prediction. For Hybrid AI, Alibaba Cloud can host the bigger jobs, including in its Bangkok region.

  • Official Alibaba Cloud Partner for Hybrid & Cloud Solutions
  • Our founder is Thailand's first and only Qwen Ambassador
The computers

NVIDIA Inception Program

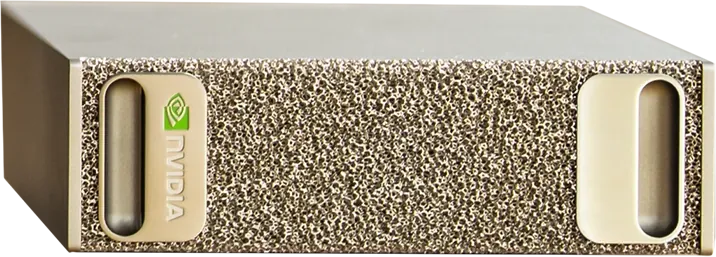
The hardware and the speed software. DGX Spark is a desktop AI computer that runs large models privately. Jetson puts AI inside robots and machines, and Isaac lets robots learn in simulation first.

  • AGICAFET is a member of NVIDIA Inception
PreMize, Efficient Local LLM

Private AI in one box.

PreMize is our ready-to-run AI system on NVIDIA DGX Spark. Upload your documents and ask questions in plain language. Every answer shows the page it came from.

Complex inside. Simple on top.

Six layers, each built by specialists, packed into one box on your desk. All your team sees is the answer.

NVIDIA DGX Spark, the computer PreMize runs on
  1. 01HardwareNVIDIA DGX Spark, in your office
  2. 02Serving3.5x the throughput of the untuned setup, same load
  3. 03ModelsTwo models: one for quality, one for speed
  4. 04KnowledgeYour documents, searched and summarized
  5. 05GovernancePolicies, permissions and a full audit trail
  6. 06ExperienceChat, an API, and LINE on M & L packages
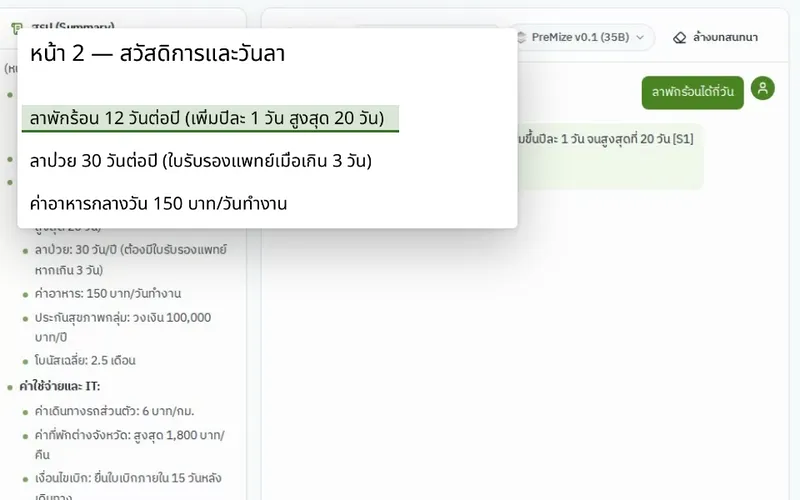
Answers with the pageAsk in Thai, click the page number, see the exact line it came from.
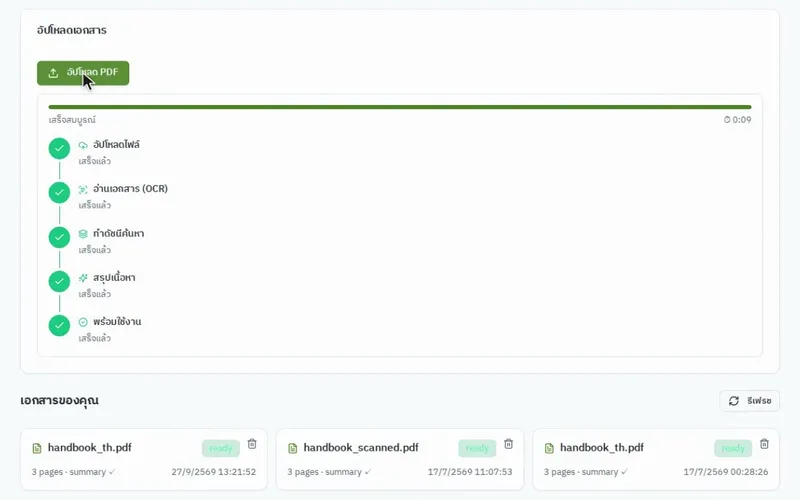
Drop in a PDFIt reads it (Thai OCR included), indexes it and writes a summary.Clip sped up
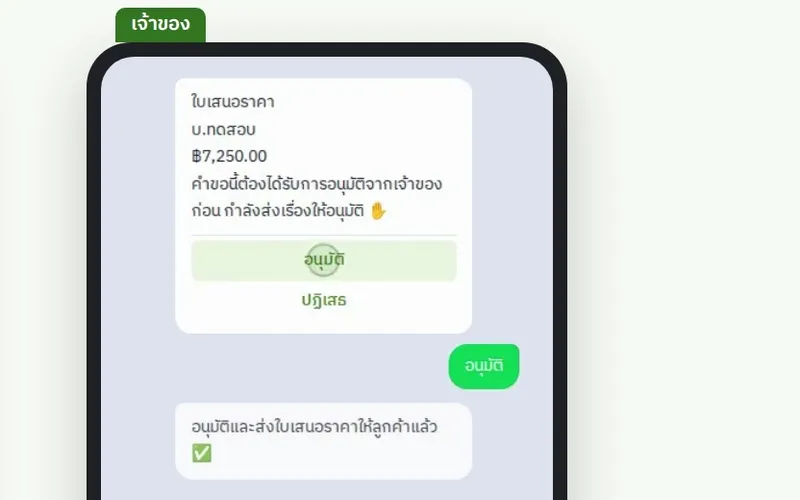
Approve from your phoneA quote over your limit waits until the owner taps Approve in chat.M & L packages
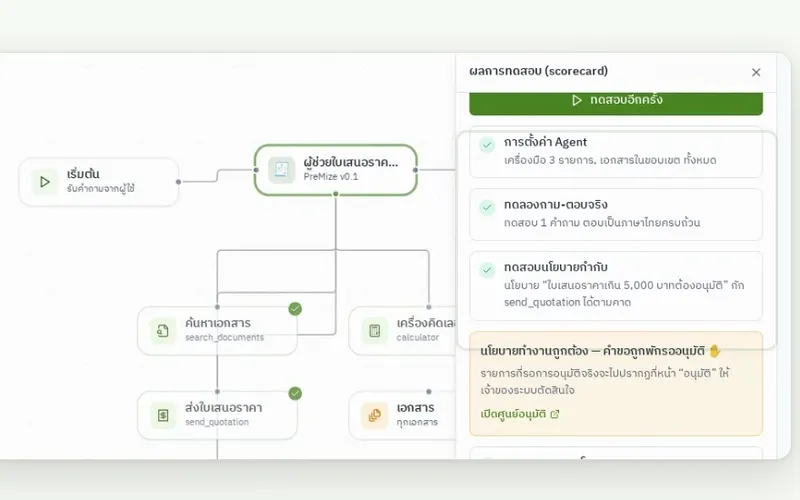
Agents that pass tests firstBuild an agent; it must pass its checks before it goes live.M & L packages · clip sped up
to the first word, with 16 people chatting at once
0.66s
total writing speed under load
125tokens/s
unified memory on one NVIDIA DGX Spark
128GB

Measured by AGICAFET on our production DGX Spark.

One-time cost
Buy the hardware once. No bill per question.
Works offline
Runs inside your network, even with the internet down.
Plugs in
An OpenAI-compatible API, so existing tools connect as they are.
We look after it
We install it, tune it, train your team and support it. You own it.

In-house training for your team.

Three courses we bring to your company: for engineers, for developers and for executives.

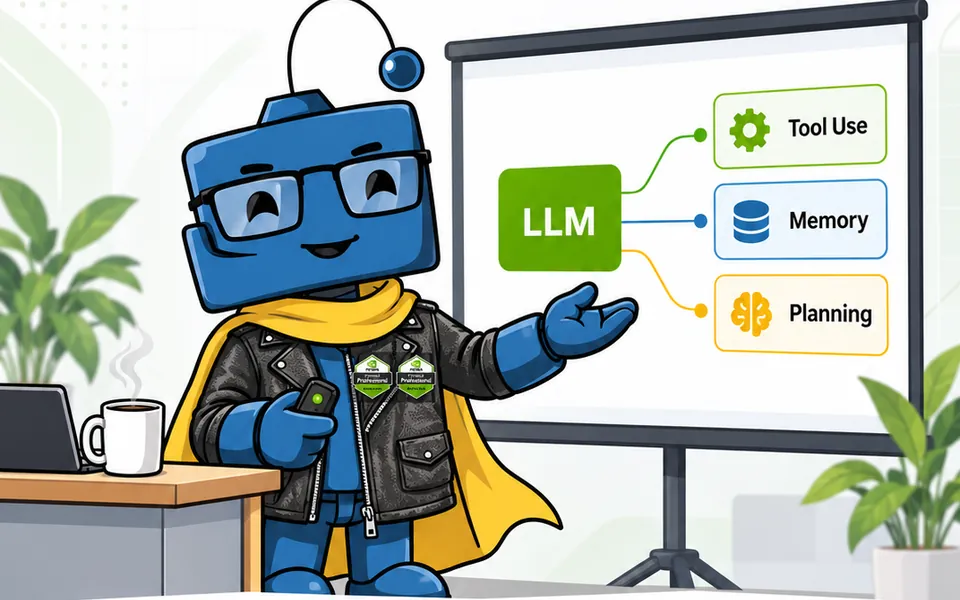
  • Illustration: a trainer presenting an LLM connected to tool use, memory and planning

    For engineers and AI teams

    Generative AI LLMs & Agentic AI

    Associate and Professional certification preparation

    Hands-on preparation for four NVIDIA certifications, led by an NVIDIA-Certified Professional.

    Associate

    • NVIDIA-Certified Associate: Generative AI LLMs
    • NVIDIA-Certified Associate: Generative AI Multimodal

    Professional

    • NVIDIA-Certified Professional: Generative AI LLMs
    • NVIDIA-Certified Professional: Agentic AI

    The exams and badges are NVIDIA’s; this course prepares you for them.

    • LLMs and multimodal generative AI, from fundamentals to use cases
    • Agentic AI: tool use, memory and planning
    • Hands-on with NVIDIA tools and frameworks
    Ask about this course
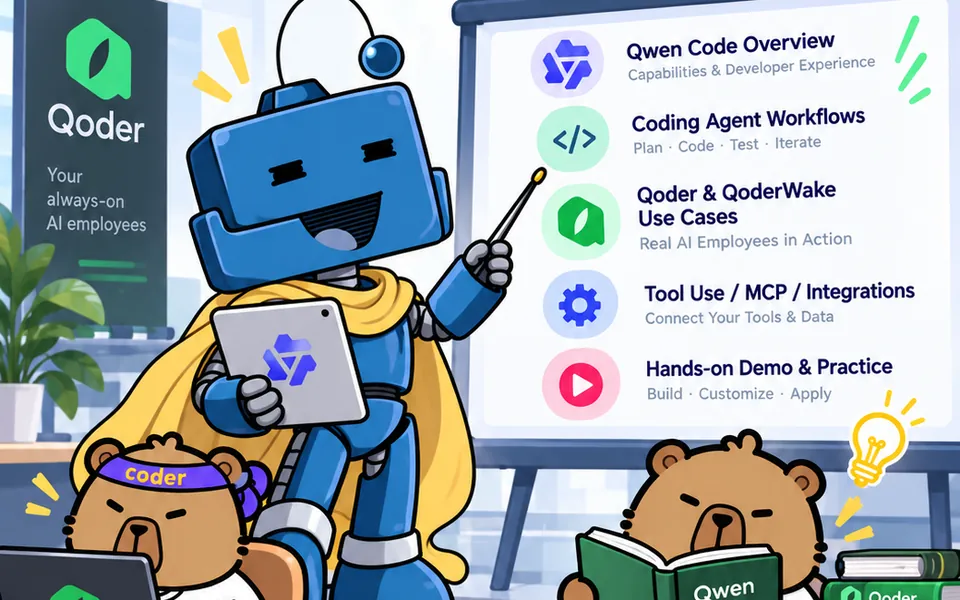
  • Illustration: a trainer presenting Qwen Code, coding-agent workflows, Qoder and QoderWake, MCP and a hands-on demo

    For developers and IT teams

    AI-Native SDLC

    From planning to production with Qoder, QoderWake and Qwen Code

    Plan, code, test and ship with coding agents. A hands-on workshop led by our founder, a Qwen Ambassador.

    Qwen SDLC

    Hands-on with

    • Qoder
    • QoderWake
    • Qwen Code and coding-agent workflows: plan, code, test, iterate
    • Qoder and QoderWake: always-on AI employees in action
    • Tool use, MCP and integrations with your own tools and data
    Ask about this course
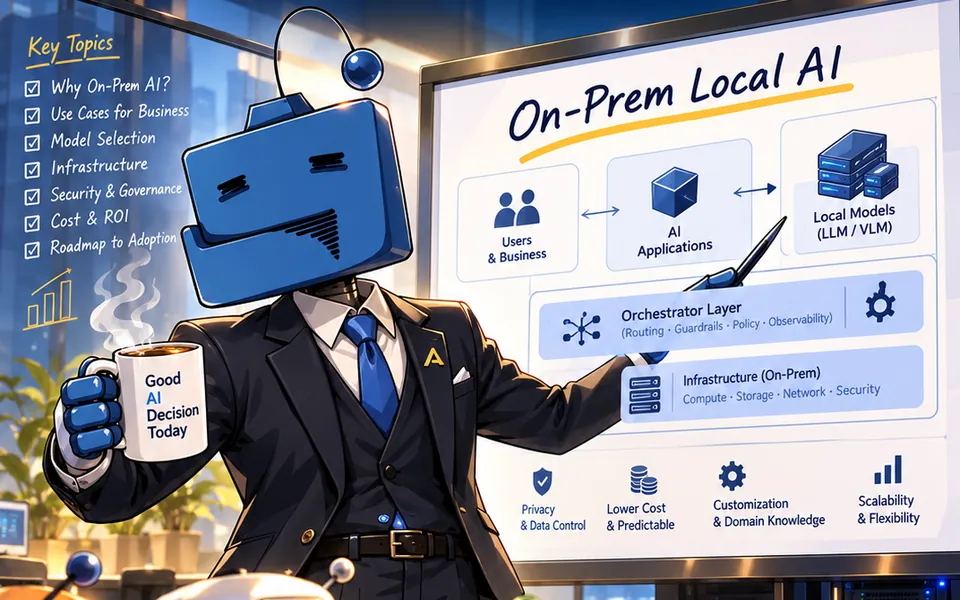
  • Illustration: a trainer presenting on-prem local AI: users, AI applications, local models, the orchestrator and on-prem infrastructure

    For executives and decision makers

    On-Prem AI for Executives

    Strategy, security and business value

    See the opportunity, see the whole picture, and decide with confidence.

    • Why on-prem AI, and the business use cases
    • Model choice, infrastructure, security and governance
    • Cost, ROI and a roadmap to adoption
    Ask about this course

Trusted across Thailand

We help companies, universities and teams put AI to real work.

organizations served
300+
community members
14,000+

Registered training vendor for 20+ organizations, including

  • CPF
  • Sony
  • CDG

Trusted by universities in Thailand and Singapore to speak, teach and design courses

  • Chulalongkorn University
  • Thammasat University
  • King Mongkut's Institute of Technology Ladkrabang
  • King Mongkut's University of Technology Thonburi
  • Chiang Mai University
  • Nanyang Technological University Singapore, Entrepreneurship Academy
  • Singapore Management University, Institute of Innovation & Entrepreneurship
NVIDIA-Certified Professional: Agentic AINVIDIA-Certified Professional: Generative AI LLMs

Natdhanai Praneenatthavee (Job)

Founder & CEO

NVIDIA-Certified Professional in Agentic AI and in Generative AI LLMs, and completed NVIDIA’s End-to-End Robotics Workflow with Isaac training at GTC Taipei.

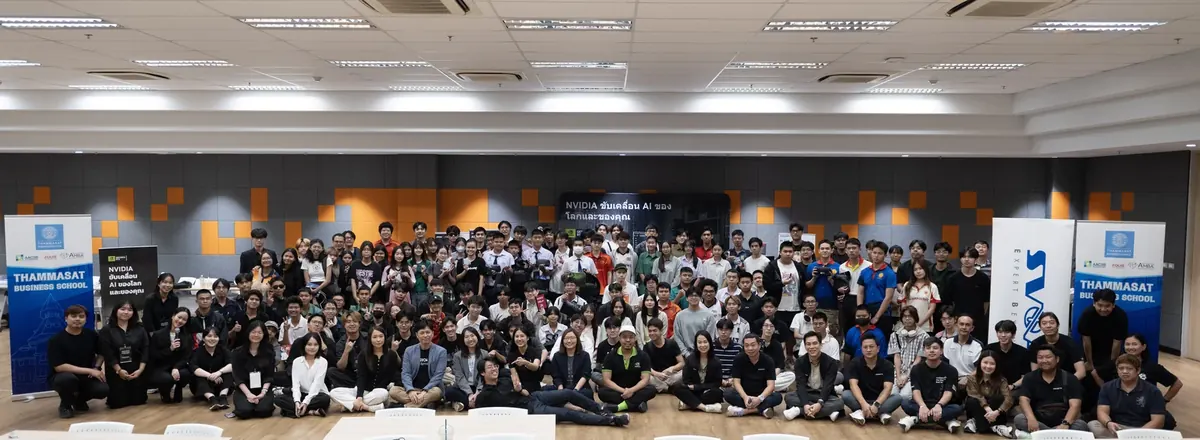
The audience of the NVIDIA RTX AI PC Event at Thammasat Business School
NVIDIA RTX AI PC Event at Thammasat Business School, with NVIDIA and SVOA.

One team across Asia.

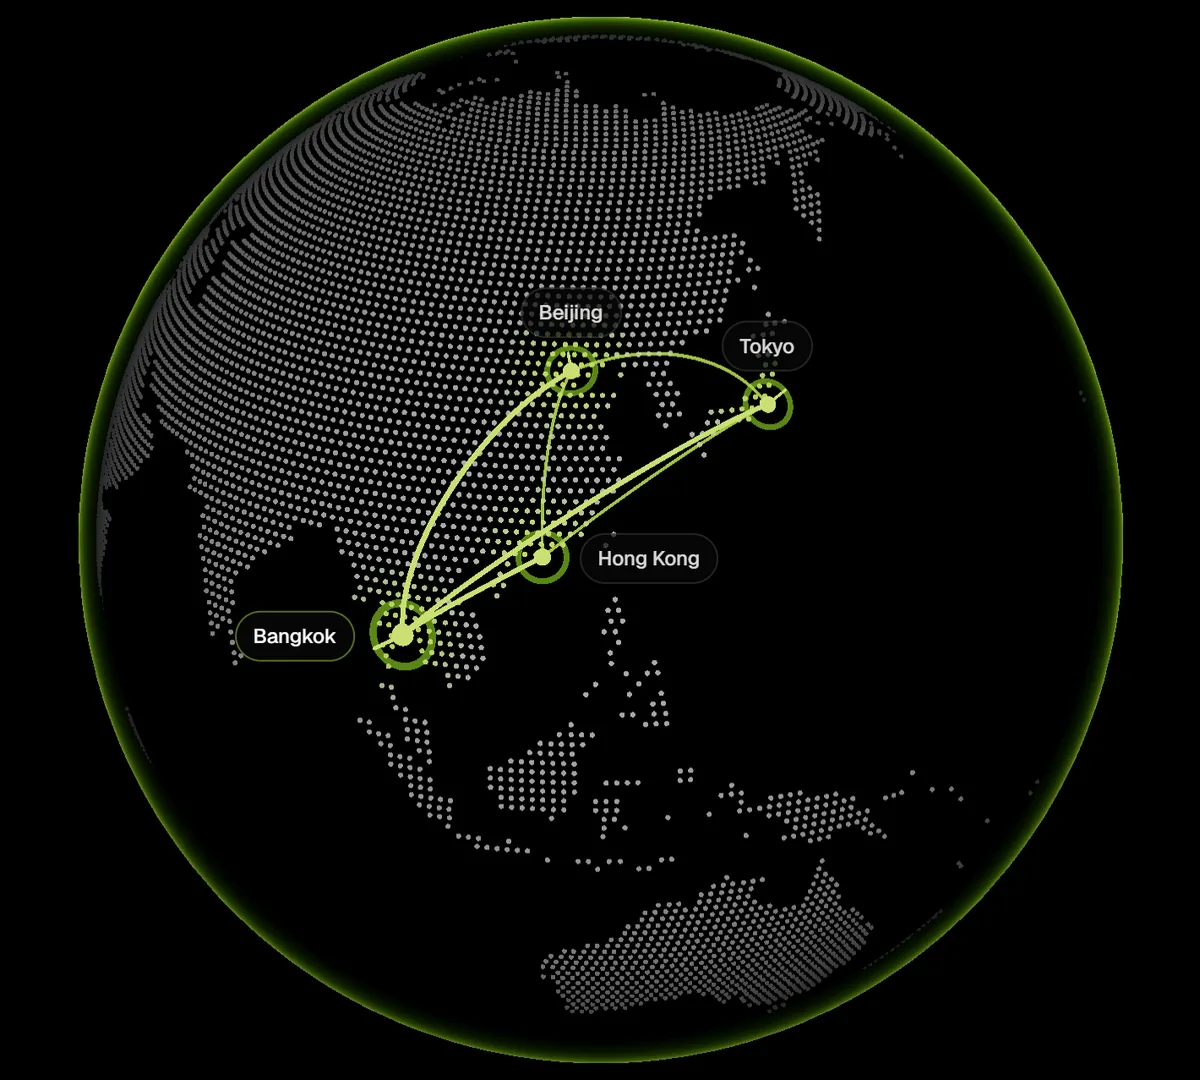
We work from Bangkok, Tokyo, Beijing and Hong Kong, as one team.

  • BangkokThailand
  • Hong Kong
  • BeijingChina
  • TokyoJapan
A globe turned to Asia, with Bangkok linked to Hong Kong, Beijing and Tokyo
vLLM Bangkok Community

We organize vLLM Bangkok.

The Thai community around vLLM, the open-source engine that serves large models fast, for the people who build AI inference and infrastructure. A flagship day with the vLLM maintainers, meetups and conference recaps in between, and a directory of the teams running vLLM in production.

Visit vllmbangkok.com
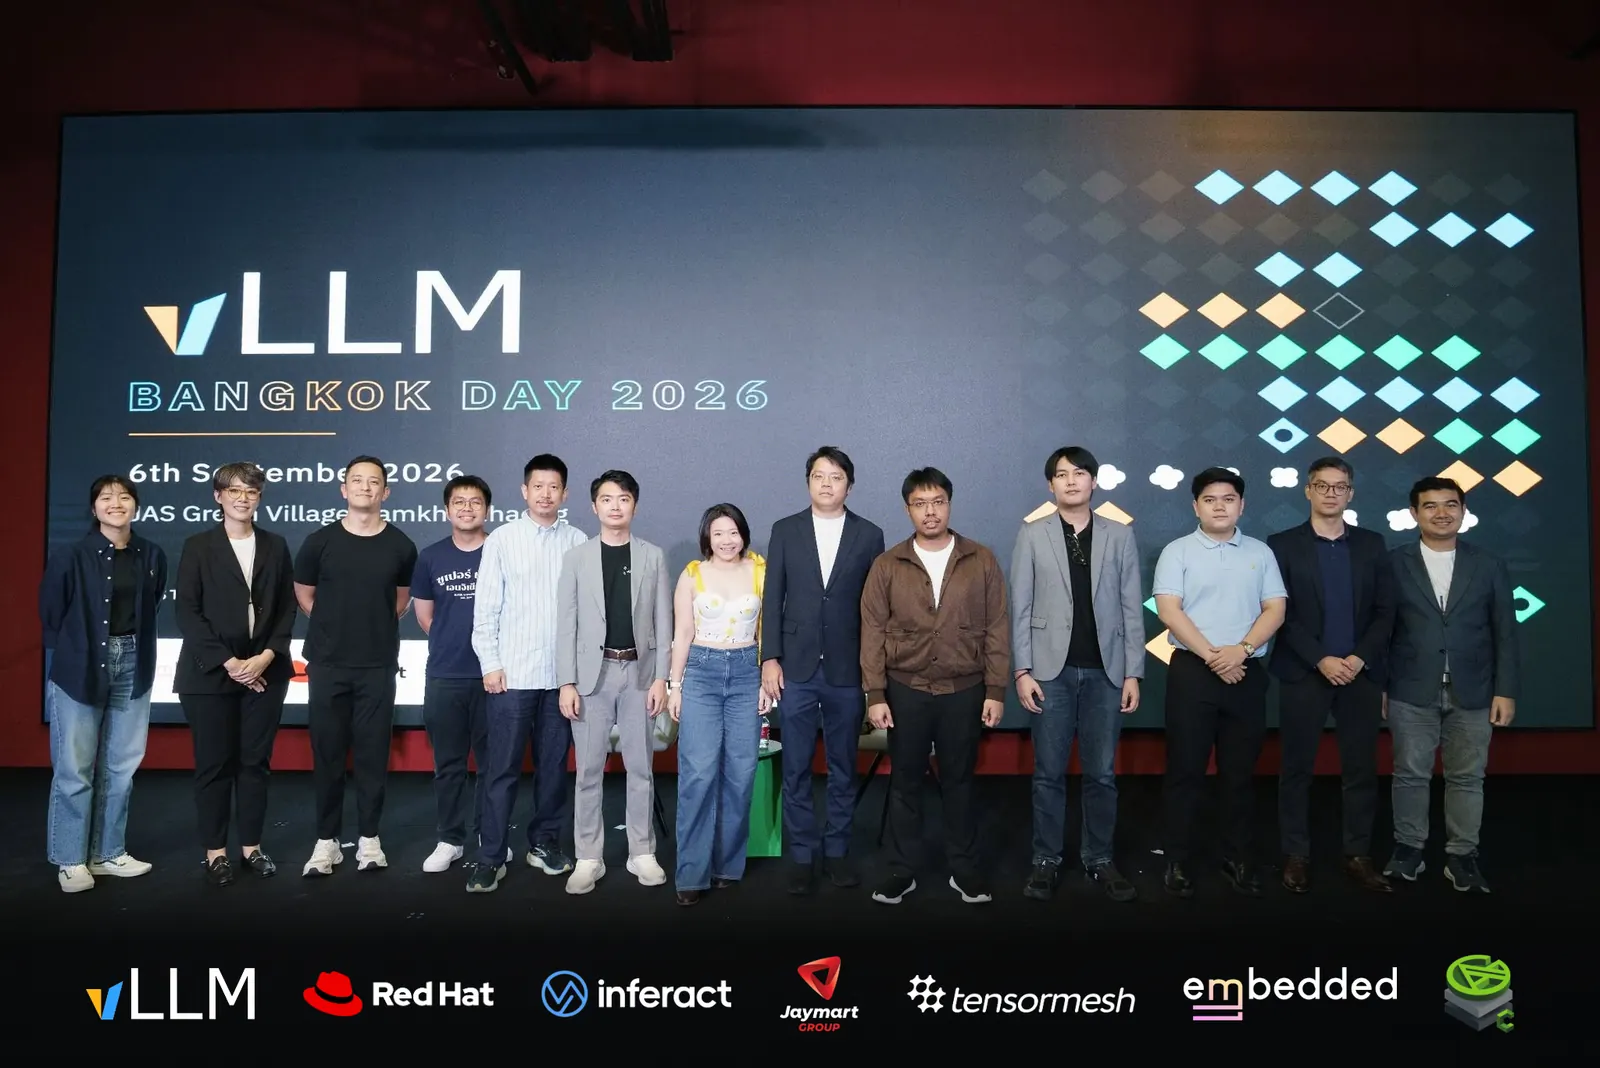
Speakers and organizers on stage at vLLM Bangkok Day 2026
vLLM Bangkok Day 2026, 6 September at JAS Green Village Ramkhamhaeng: talks from vLLM maintainers, Thai production stories and two panels.

Questions we hear often

Does my data leave my building?
Not with Local AI: everything runs on a machine in your office. With Hybrid AI, only the jobs you choose go to the cloud, under rules you set, and we can set that up in Alibaba Cloud’s Bangkok region.
Do I need my own AI team?
No. We size the system, install it, connect it to your work, train your staff and support you after launch.
Does it work in Thai?
Yes. Thai is among the languages the Qwen model family supports. Send us a few of your own Thai documents and we will show you the results.
What are Qwen and DGX Spark?
Qwen is Alibaba’s family of AI models. Many of them are open-weight, so you can download them and run them on your own hardware. NVIDIA DGX Spark is a small AI computer that sits on a desk and runs them privately.
How do I start?
Explore PreMize at premize.agicafet.com, or tell us about your project. We reply with next steps.

Tell us where your AI needs to run.

Explore PreMize, or send us your idea. We’ll reply with next steps.